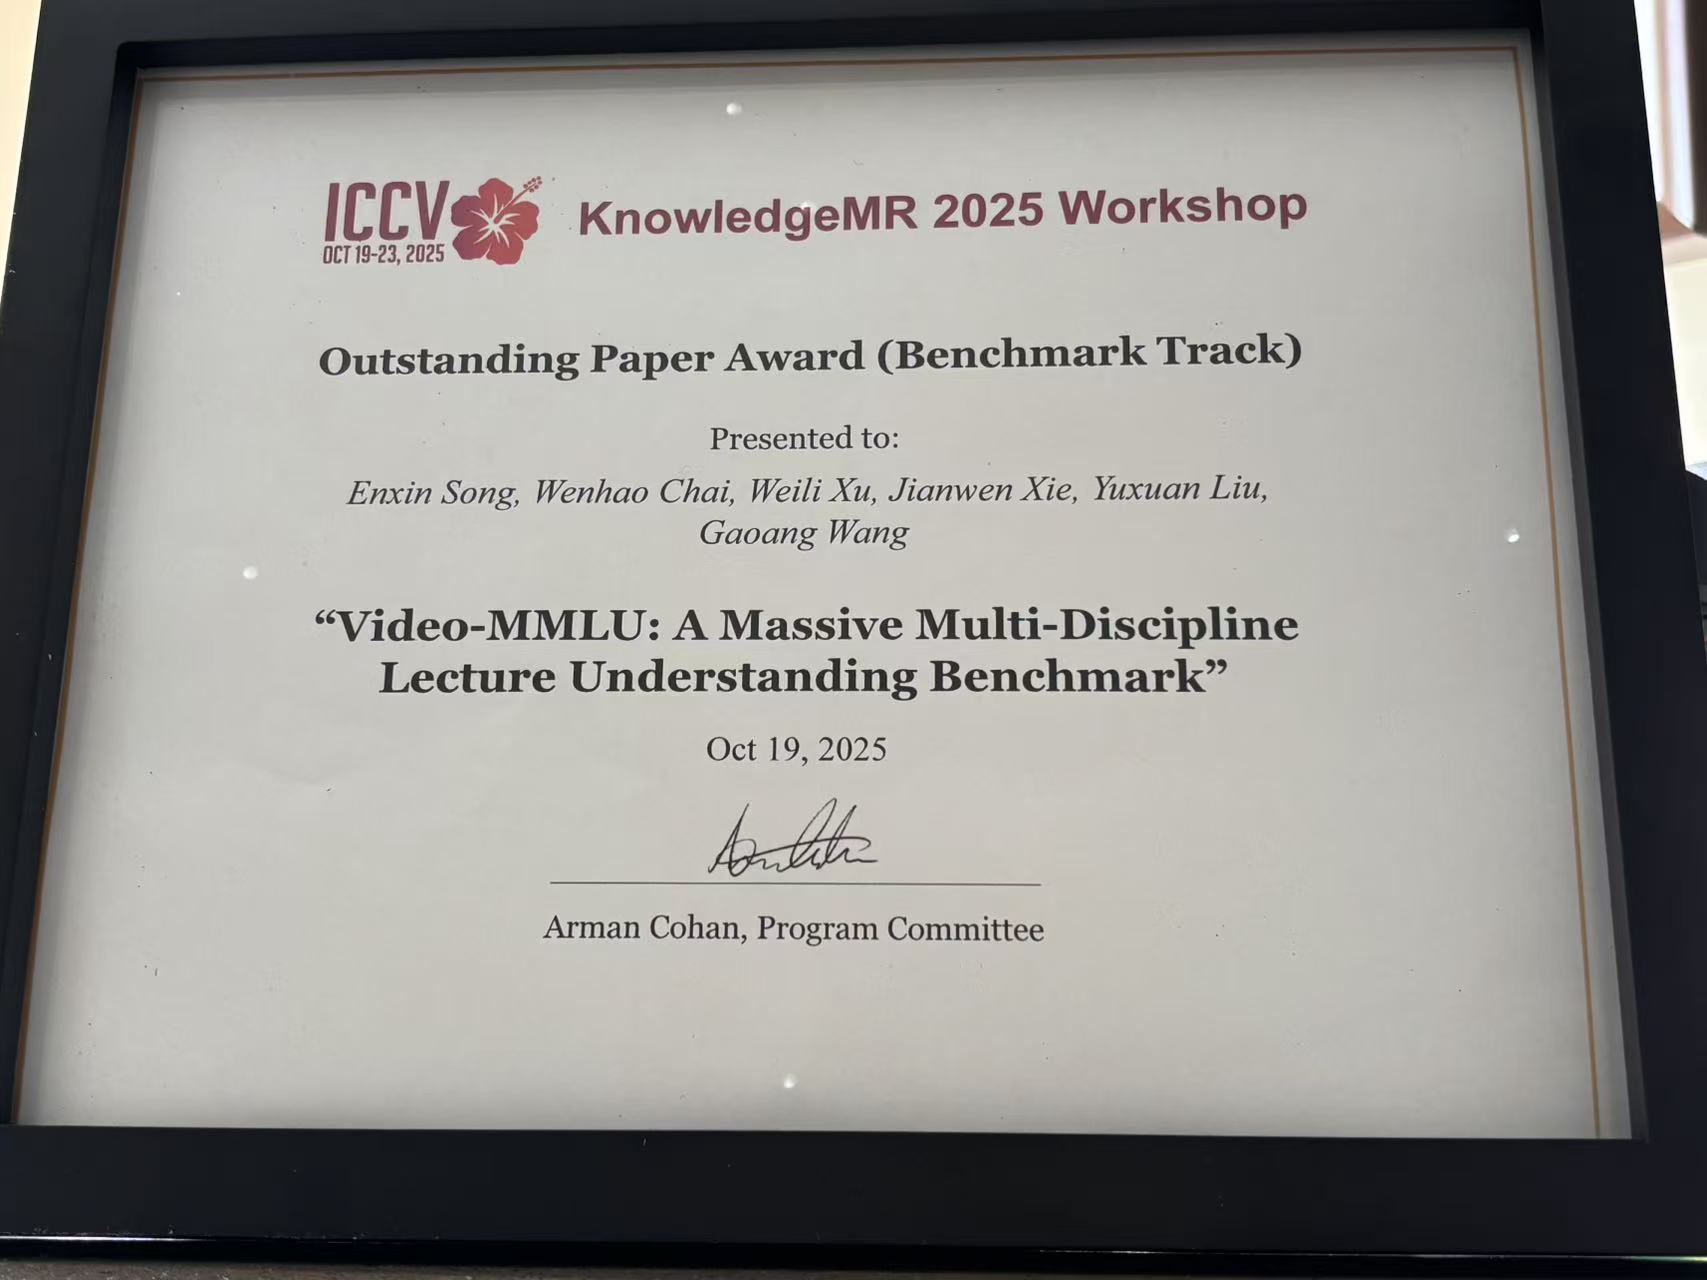
He leads MovieChat, one of the first large multimodal models and benchmarks for hour-long video understanding with a memory mechanism. He co-leads LiveCodeBench Pro, a benchmark that Google and Meta use to evaluate Gemini and Muse Spark. He has organized workshops and competitions at CVPR 2024, CVPR 2025, and CVPR 2026. His work has been featured in MIT Technology Review. Sequoia China and MIT Technology Review China named him to AI25, their list of AI innovators under 25.
He is currently working on Recursive Self-Improvement (RSI).
Nine AI agents judged 101 penalty incidents from 2026, each clip cut before the referee's call. Scored against expert verdicts, the best two, GPT-6.1 Terra (64.4%) and Gemini 4 Carbon (63.4%), tie the referee with VAR (63.4%).
Open models score well on AutomationBench; the scoring rule, unsound string-matching guardrails included, decides much of the ranking, and eighteen of its string guardrails fail runs a task owner would accept.
Undergraduate and master's students: if you want to talk about research ideas, career plans, or life in AI/ML, book a slot. I set aside at least 30 minutes every week for these meetings, and I encourage students from underrepresented groups to reach out. Open times are on my calendar.